Don't worry! The contents here will appear on the published page.
Are You Overspending on Closed AI Models? Kimi K3.1 Pro Just Ranked #4 in Accounting
John Iwuozor
Content Lead, Finance and Research
John Iwuozor
Content Lead, Finance and Research
John Iwuozor leads content, finance, and research at DualEntry. He writes for the people who actually close the books: controllers running month-end, CFOs weighing an ERP migration, accountants buried in reconciliations. Before DualEntry he spent five years covering B2B SaaS and fintech for Forbes Advisor, Ramp, and Infosecurity Magazine. He builds every piece on primary data, including benchmarks, practitioner interviews, and product testing, rather than recycled advice. He is also an avid chess player.
Learn about our editorial policies.
Last updated
October 25, 2026
Reviewed by
Summarize this article


TL;DR
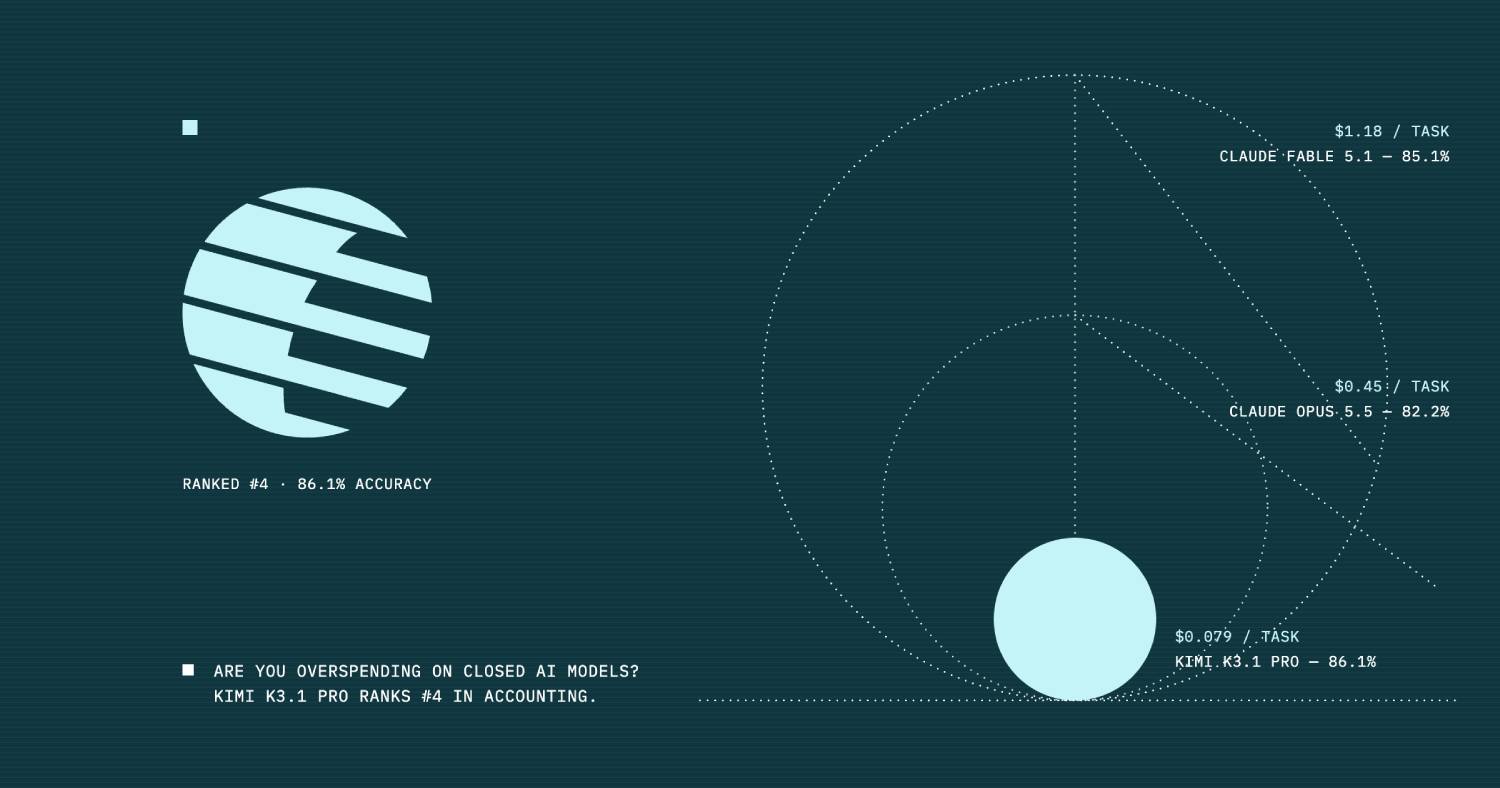
Open-weight AI models are getting harder to ignore. Moonshot AI's new Kimi K3.1 Pro just debuted at #4 on the DualEntry Accounting AI Benchmark, scoring 86.1% accuracy across accounting tasks.
That puts it ahead of Claude Fable 5.1 (85.1%), Claude Opus 5.5 (82.2%), GPT-6 Astra (81.2%), and Claude Sonnet 5.5 (80.2%).
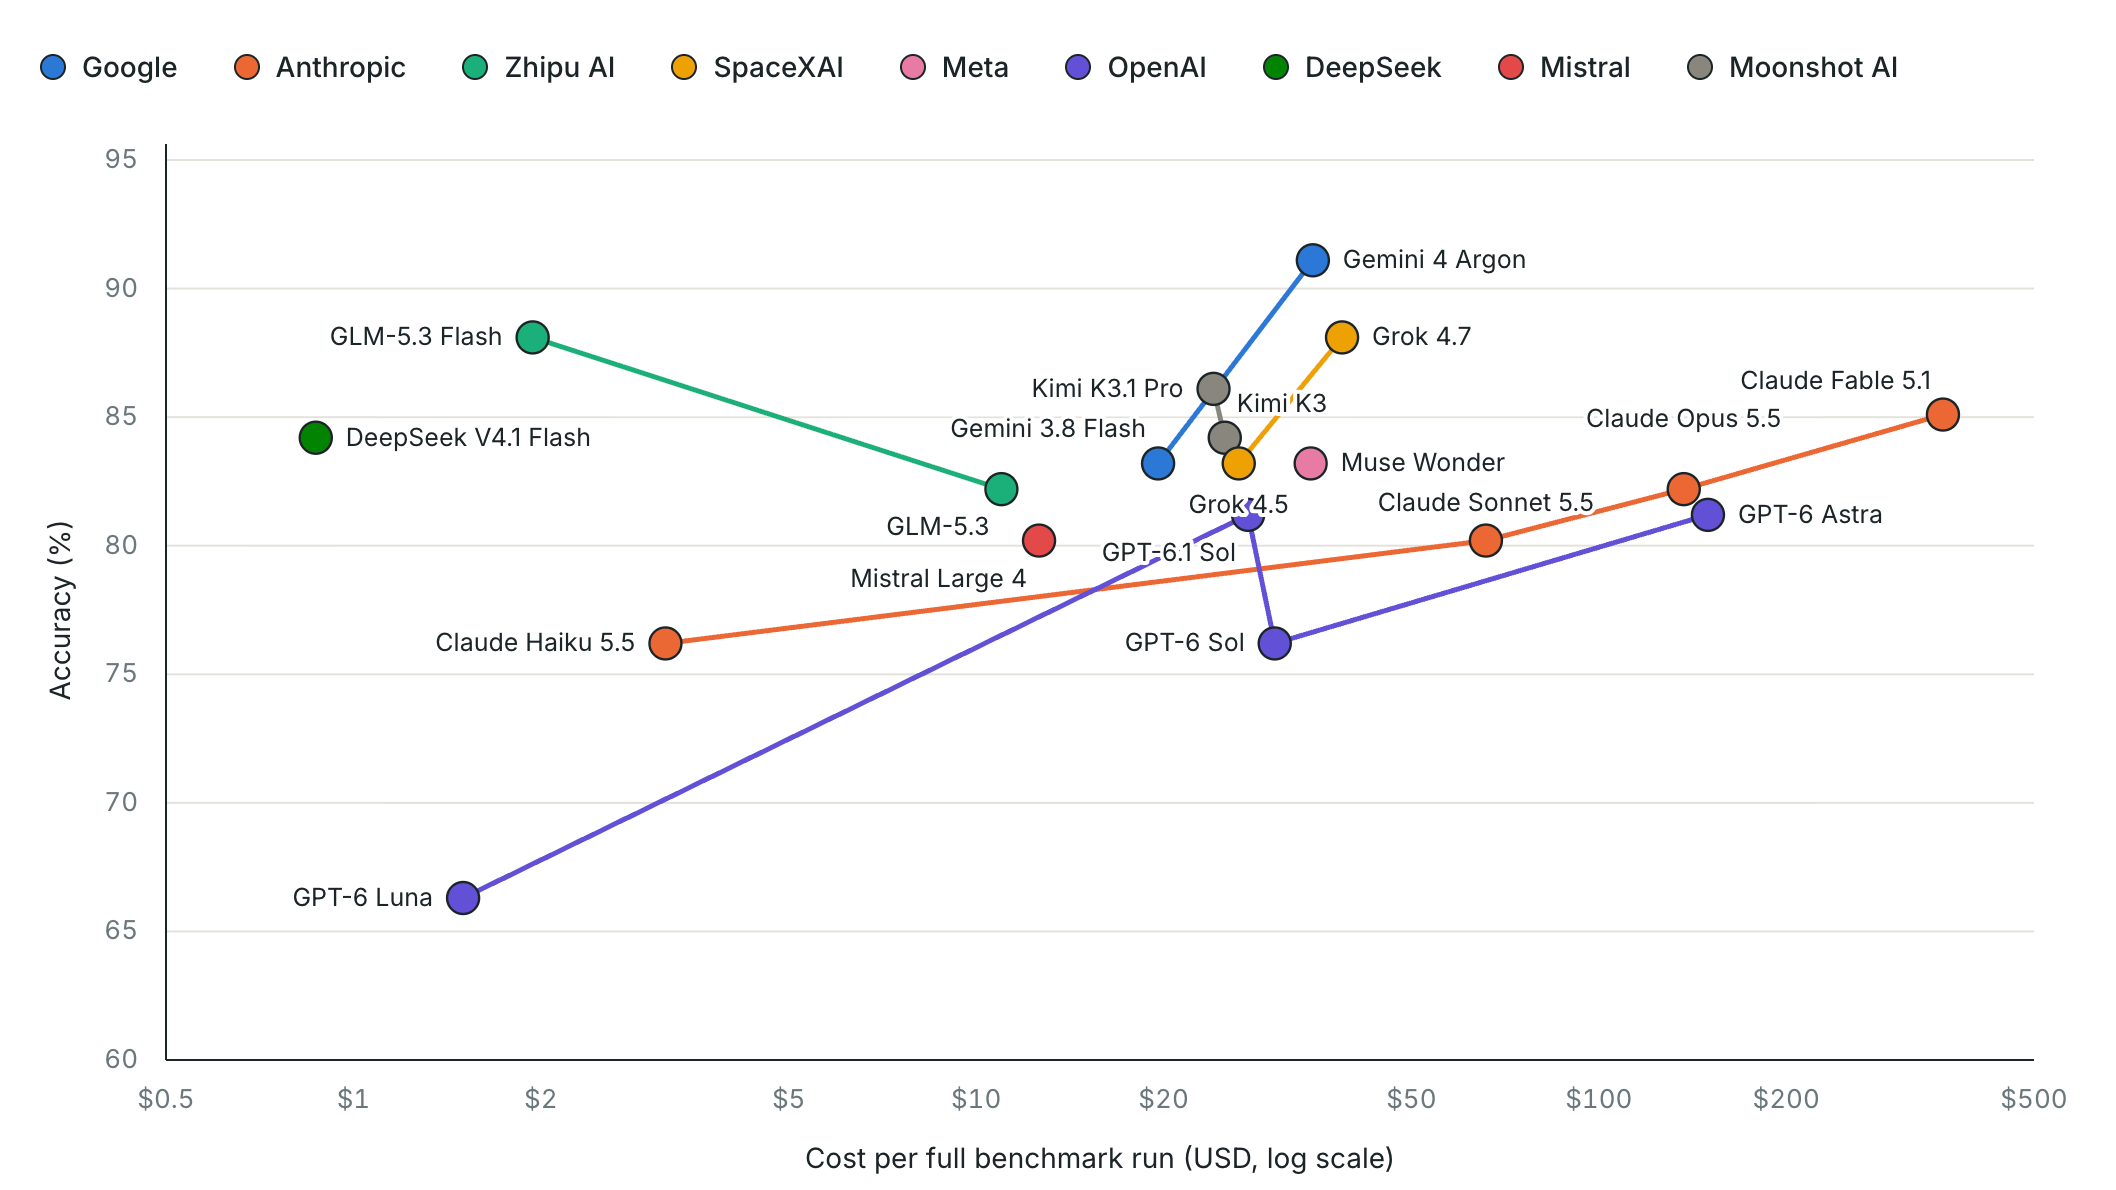
And Moonshot isn't alone. Zhipu AI's GLM-5.3 Flash currently ranks second with 88.1% accuracy, behind only Google's Gemini 4 Argon at 91.1%.
Two open-weight models now sit among the top four performers on our benchmark. That's an interesting development for businesses relying heavily on proprietary AI models.
Key findings
- Kimi K3.1 Pro scored 86.1%, ranking #4 overall on the DualEntry Accounting AI Benchmark.
- Two open-weight models now rank in the top four, with GLM-5.3 Flash at #2 and Kimi K3.1 Pro at #4.
- It scored 1.9 percentage points higher than its predecessor, Kimi K3 (84.2%).
- Its strongest areas were bank reconciliation (100%), followed by journal entries and financial reporting (92.3% each).
- It scored 75% on hard tasks, compared with 94.6% on easy and 86.1% on medium tasks.
Where Kimi K3.1 Pro performed best
Kimi K3.1 Pro's strongest performance came in bank reconciliation, where it scored 100%, followed by journal entries and financial reporting at 92.3%.
Performance varied more by task difficulty. It scored 94.6% on easy tasks and 86.1% on medium tasks, but accuracy dropped to 75% on hard tasks.
Month-end close was its weakest area at 66.7%, suggesting Kimi is competitive across routine accounting workflows, although more complex tasks remain a challenge.
Kimi K3.1 Pro improves on its predecessor
Kimi K3 scored 84.2% on the same benchmark. Kimi K3.1 Pro reached 86.1%, an improvement of 1.9 percentage points.
The new model also finished ahead of several established competitors:
The benchmark tests 101 synthetic accounting cases across eight areas, including transaction classification, journal entries, accounts payable, accounts receivable, bank reconciliation, financial reporting, month-end close, and accounting knowledge.
Each model is evaluated three times using the same test company, tools, and instructions.
Are closed AI models still worth the premium?
Google's Gemini 4 Argon remains the overall leader at 91.1%, and closed models still occupy several of the top positions.
But the competitive landscape is changing. With GLM-5.3 Flash at 88.1% and Kimi K3.1 Pro at 86.1%, open-weight models are performing at levels that rival or exceed many proprietary alternatives.
The cost difference is substantial. Kimi K3.1 Pro averaged $0.079 per task, compared with $1.18 for Claude Fable 5.1 and $0.45 for Claude Opus 5.5. That's roughly 15 times and six times cheaper, respectively, while scoring higher on accounting accuracy.
There are trade-offs, though. Kimi averaged 125.6 seconds per task, compared with 26 seconds for Claude Fable 5.1 and 19.7 seconds for Claude Opus 5.5. It was also less consistent than both, scoring 73.3% against 80.2% and 78.2%, respectively. Consistency measures the percentage of tasks a model passes on all three attempts.
For finance teams building AI-powered workflows, that makes model selection a much more interesting decision. Why default to one provider when another model might deliver better accuracy at a fraction of the cost? The answer depends on how much speed and consistency matter for the workflow.
Explore the full DualEntry Accounting AI Benchmark to compare accuracy, consistency, speed, and cost across leading models.
See the full power of DualEntry in 30 minutes
John Iwuozor leads content, finance, and research at DualEntry. He writes for the people who actually close the books: controllers running month-end, CFOs weighing an ERP migration, accountants buried in reconciliations. Before DualEntry he spent five years covering B2B SaaS and fintech for Forbes Advisor, Ramp, and Infosecurity Magazine. He builds every piece on primary data, including benchmarks, practitioner interviews, and product testing, rather than recycled advice. He is also an avid chess player.